

Why I Built VideoMask
I’ve spent the last few months deep in Physical AI — robotics, multimodal models, world models, all the data infrastructure stuff that actually makes this work.
One pattern kept coming up:
Segmentation is a massive bottleneck.
Every robotics team I talked to said some version of:
“We have the videos, we just don’t have masks”
“SAM works but wiring it up is a pain”
“We need something simple that just gives us dataset-ready masks”
So I built VideoMask SDK.
It’s a Python-first toolkit that takes raw videos and turns them into usable segmentation datasets. Fast. No ceremony.
VideoMask is the first piece of ConceptOps, the concept-centric data engine I’m building for Physical AI.
What VideoMask Does (v0.1)
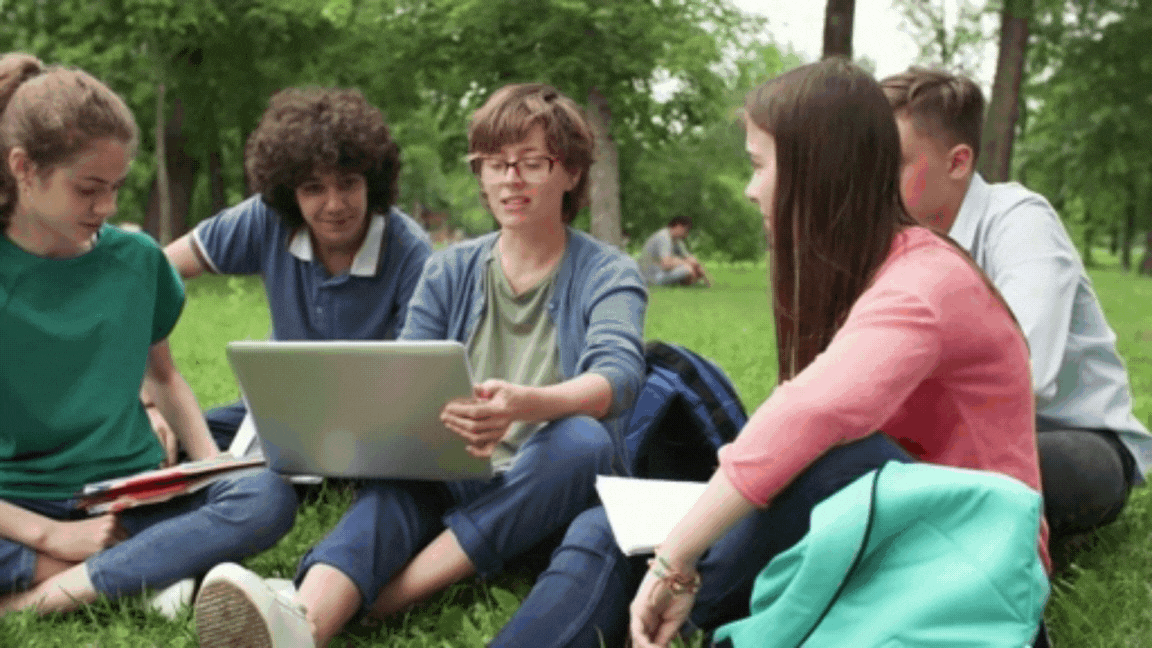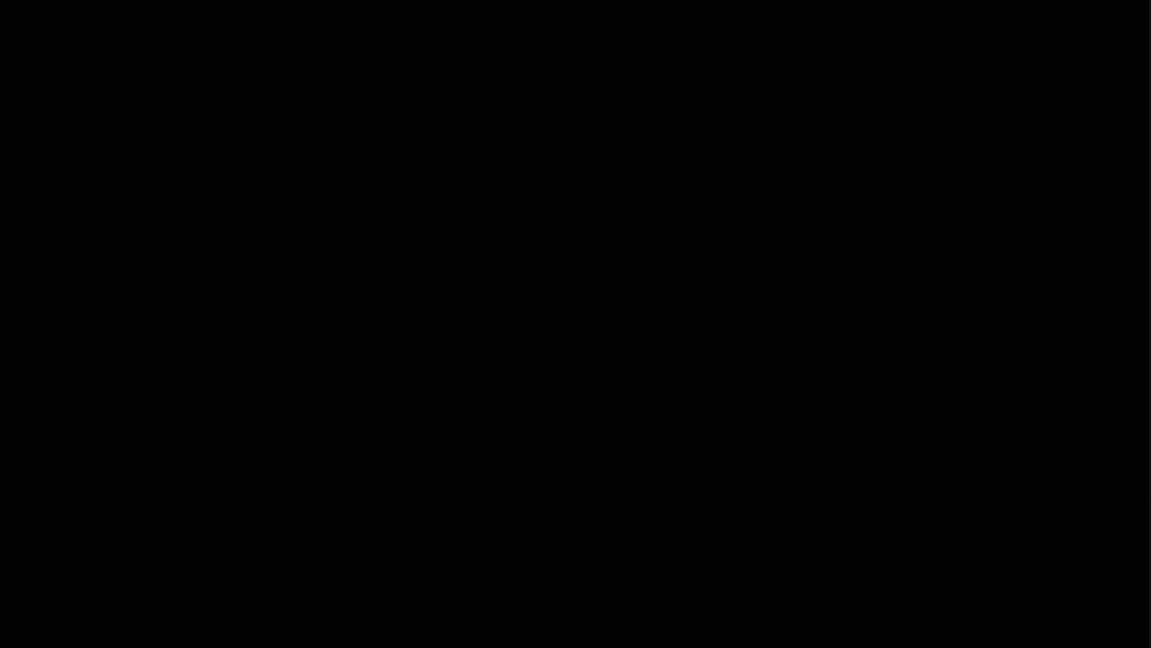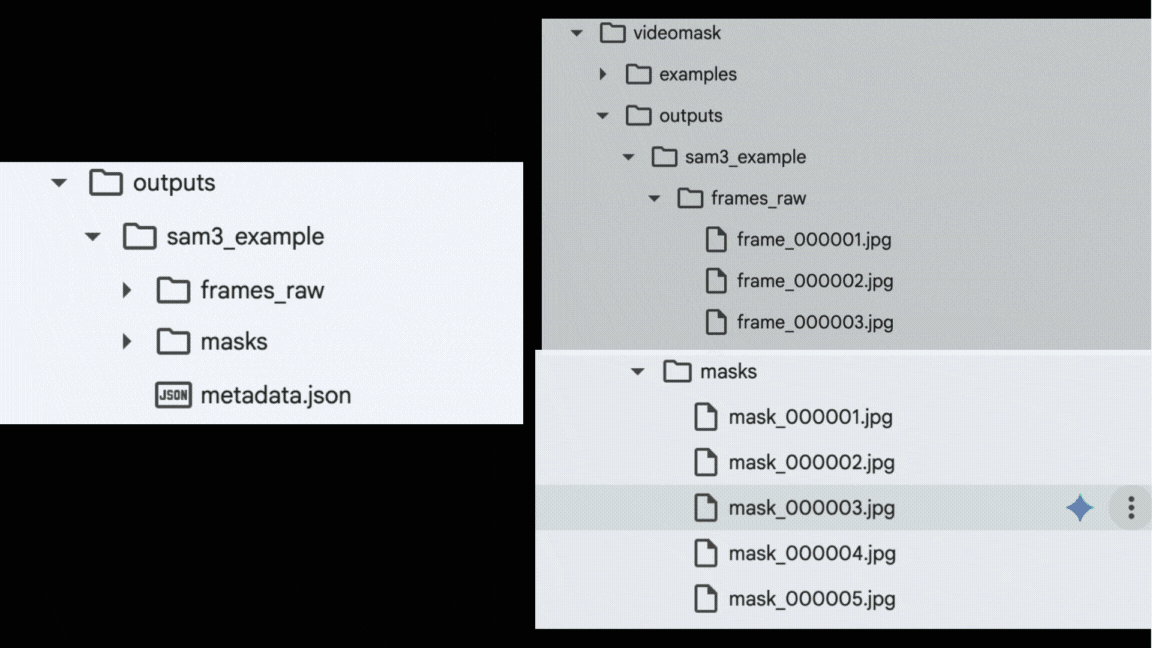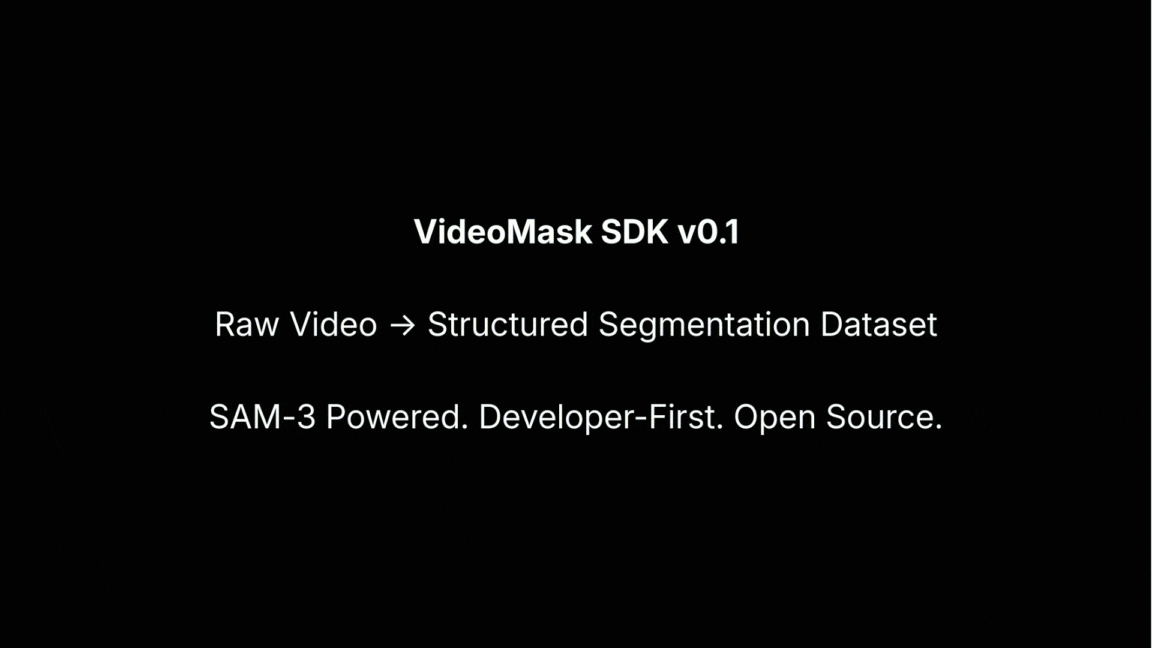
Figure 1: How VideoMask works
Input:
A video file (.mp4)
A text prompt (for SAM-3 backend)
Basic config (fps, resize, max frames)
Output:
frames_raw/
masks/
metadata.json
What’s inside:
ffmpeg frame extraction
SAM-3 backend (GPU) + dummy backend (CPU)
Light temporal smoothing
Folder-format dataset export
CLI and Python API
Pluggable backend architecture
You go from video → frames → masks → dataset without writing a bunch of glue code yourself.
SAM-3 Integration
SAM-3 is great, but getting it to run reliably means dealing with:
CUDA PyTorch setup
HuggingFace tokens and weight access
Dependency hell (iopath, etc.)
The preprocessing pipeline
VideoMask wraps it cleanly:
seg = VideoSegmenter(
    backend=”sam3”,
    backend_kwargs={”text_prompt”: “person”, “device”: “cuda”},
    )
seg.run(”input.mp4”, out_dir=”dataset/”)
It handles:
Multi-mask output
Safe mask selection
Empty output fallback
Resizing and fps control
Dataset writing
The boring infrastructure work that makes SAM-3 actually usable in production.
Design Philosophy
VideoMask is:
Python-first — no heavy infra required
Composable — backends, pipeline, exporters all modular
Extensible — concept backends coming in v0.2+
Transparent — you can see what’s happening
Built to evolve — this grows into ConceptOps
I don’t think segmentation tooling should need a cluster, a web UI, or 50k lines of code.
If you know Python, you should be able to use it.
Example Results
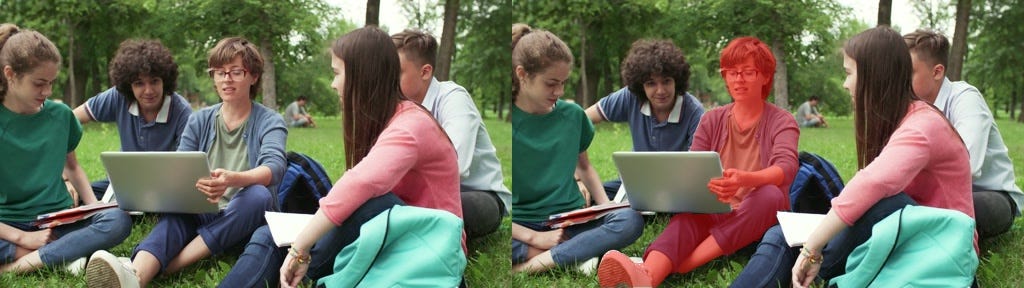
Figure 2: Raw frame → masked overlay
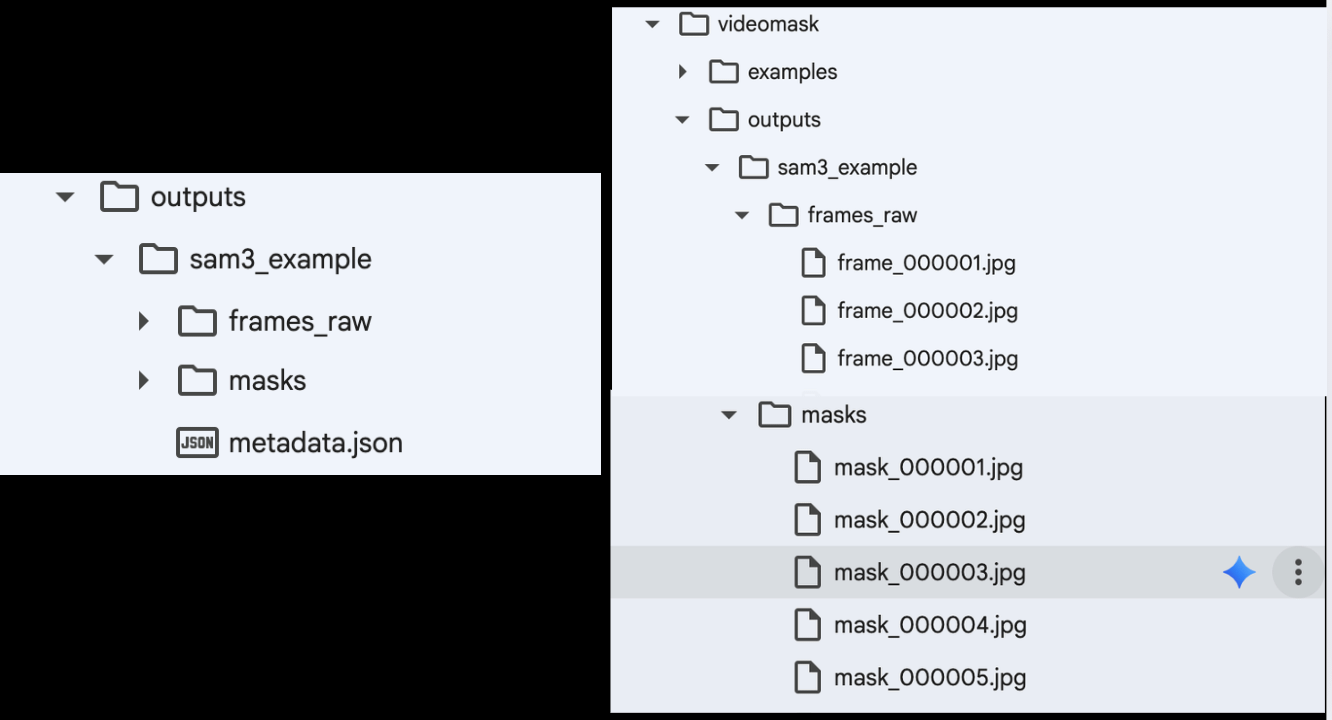
Figure 3: Output folder structure
What’s Next
v0.2:
COCO export format
Mask selection strategies (top1, union, topk, largest)
EfficientSAM backend
Concept backend (early version)
Simple viewer utility
v0.3:
ConceptOps alpha
Masklets (concept tracks over time)
Dataset slicing by concept
HuggingFace dataset uploader
The bigger picture:
VideoMask is the base layer of ConceptOps — a concept-centric data engine for Physical AI.
Segmentation is step one.
Try It
Repo: https://github.com/msunbot/videomask/
Colab (SAM-3, GPU):
Feedback and contributions welcome — still early and iterating fast.